Blog
Thoughts on AI, engineering, and building products.
Silver Eval Datasets Without the Bulk-Generation Trap
LLM-generated QA pairs collapse toward the model's own idea of a question unless you condition generation on personas, scenarios, and the feature being shipped. The personas themselves are derived from the gold set. The method, the prompts, and the loop that keeps synthetic eval data honest.
Evaluating Agent RAG Systems: Score All Three Edges
A RAG system has three measurable pairs, query against context, context against answer, query against answer. Most teams only grade the final answer. Edge-by-edge metrics with deterministic ones preferred, and the LLM judge treated as the last resort instead of the whole plan.
Memory Systems for AI Agents: What's Actually Worth Building
Grep, simple RAG, agentic RAG, graph RAG, and the LLM wiki, judged by what they cost to run and maintain versus what they actually buy. The boring two cover most of the work.
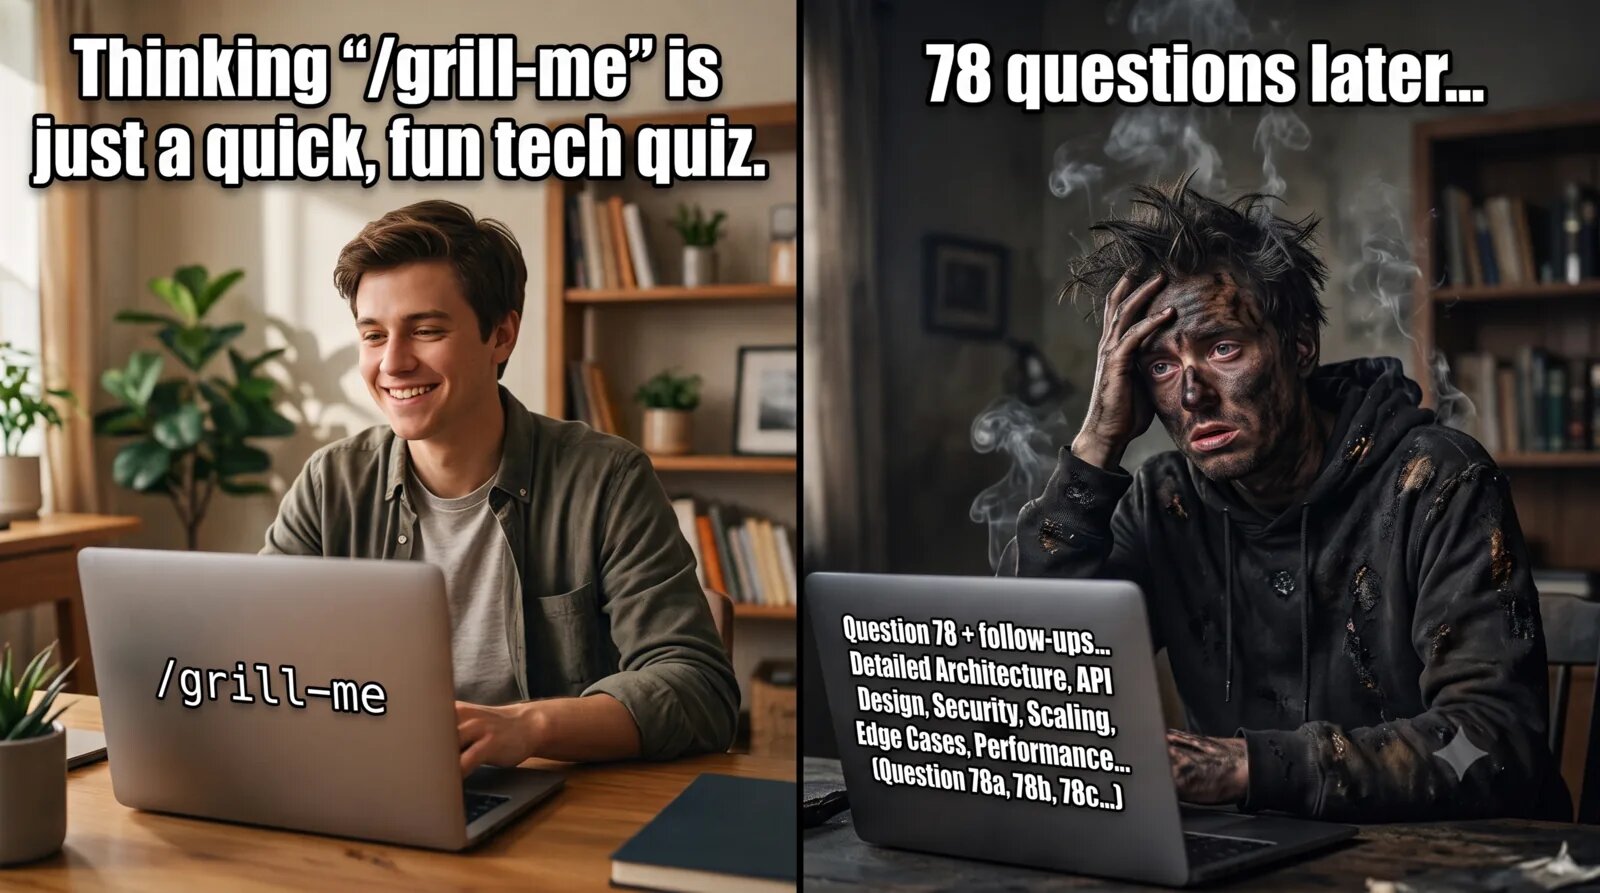
When to Stop Planning With an AI and Start Building
A 4-hour, 78-question grilling session taught me where preparation ends and waterfall-by-another-name begins.
Credit Risk Assessment When the Data Was Never Built for It
A credit model assumes a feature matrix and a column of labels. An operational loan warehouse hands you neither. The real work is manufacturing both: reconstructing features from scattered tables, building the target label out of servicing history, and keeping a strict line between what is knowable at application time and what only the future reveals.
Scoring Motorcycle Condition from Inspection Videos
A multi-modal pipeline that fuses engine-sound audio, a Thai-language note, and a categorical checklist to grade a used motorcycle, and why the right move was to stop predicting an exact score and judge it as a pass/fail instead.
A Full-Lifecycle MLOps System for Credit Default, Part 2: Why Accuracy Is the Wrong Goal for a Lender
A credit model outputs a probability; one threshold turns it into an approve/reject decision. Choosing that number by simulated profit-and-loss instead of accuracy was worth a 30% profit lift on out-of-sample data.
Routing Customer Feedback with Few-Shot Retrieval
Turning a multi-label text-classification problem into structured LLM generation grounded by retrieved examples, with a human-in-the-loop that improves routing without ever retraining a model.
A Full-Lifecycle MLOps System for Credit Default, Part 1: From Messy Data to a Self-Updating Model
How to take a raw, real-world credit dataset all the way to a self-retraining model: pluggable preprocessing, an MLflow experiment matrix, and blue-green model promotion orchestrated by Prefect.
Building a Bilingual Semantic Product Search Engine
Replacing keyword-only product search on a second-hand marketplace with hybrid lexical/semantic search, fed by a real-time PostgreSQL change-data-capture pipeline, and the relevance tuning that decided whether any of it was trustworthy.